Introducing Thinker-Task: Training models to think fast and slow
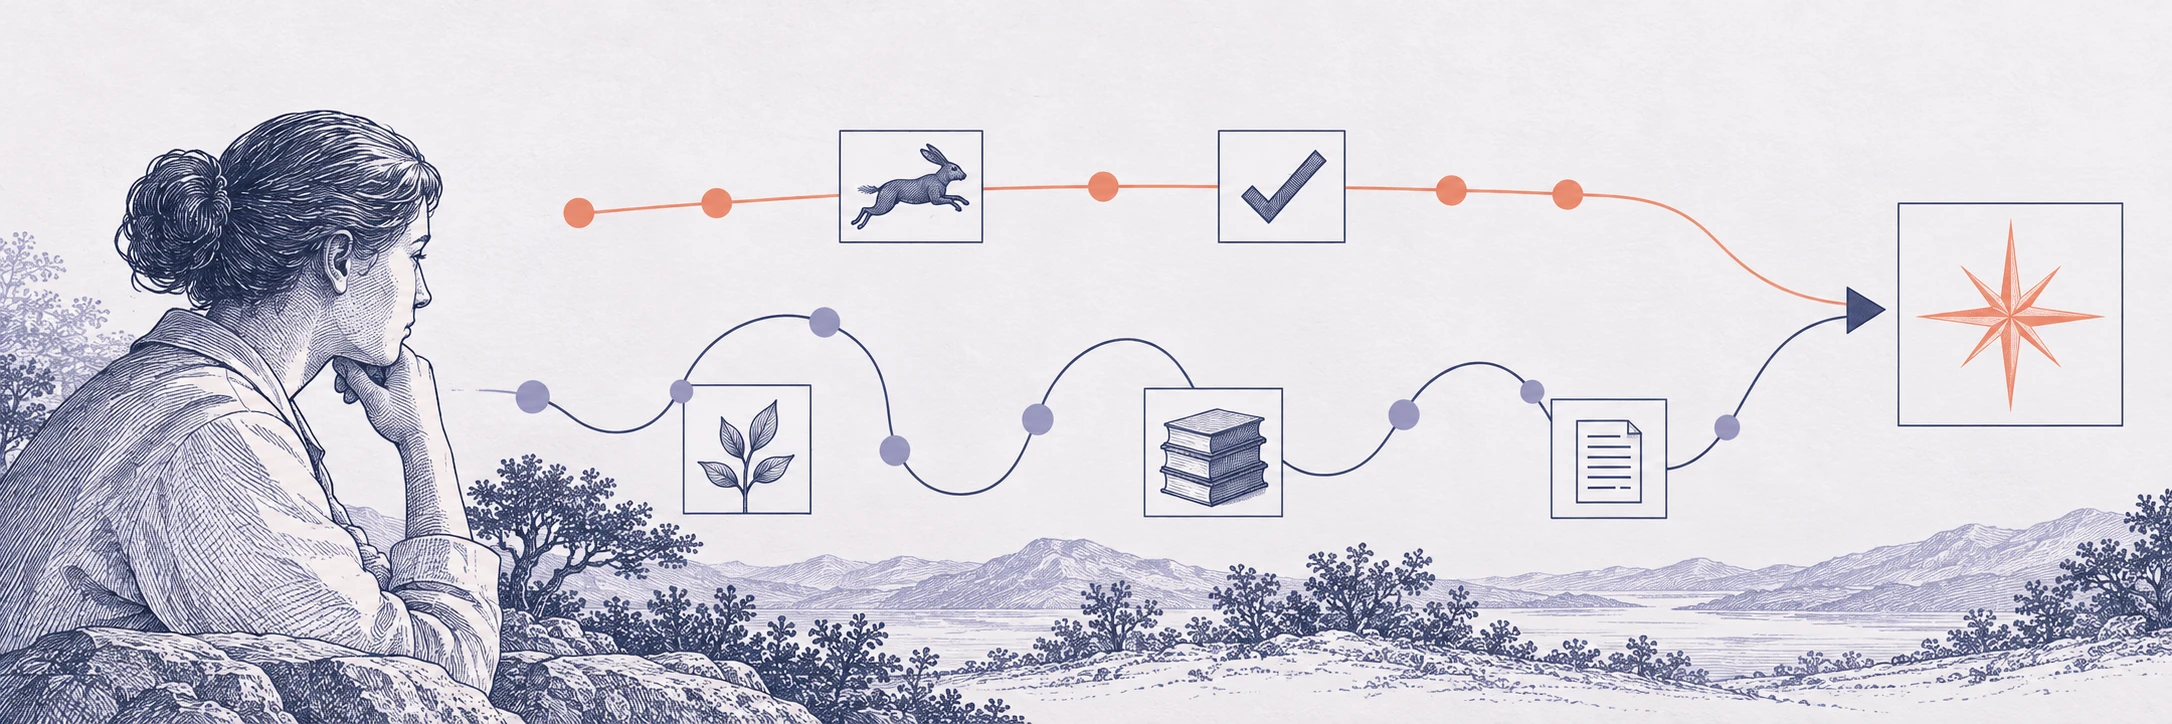
We are introducing Thinker-Task, a reinforcement learning task that trains language models to combine quick intuition with deliberate reasoning. By explicitly training models to answer, check and refine their responses, we improve reasoning accuracy while developing a fast-thinking mode that uses fewer tokens.
Reasoning models can solve difficult problems by spending more time thinking, but their reasoning often includes repeated checks and unproductive detours. When training rewards only the final answer, it provides little guidance about which parts of that process were useful. Human reasoning offers a useful starting point: we often reach an answer intuitively, then examine it more carefully when needed. Inspired by this interplay, we designed Thinker-Task to train these abilities separately and bring them together during problem solving.
Training proceeds through four stages. First, the model answers under a short token budget, developing its ability to identify a promising solution quickly. It then checks that answer and, when necessary, receives more room to reason through a correction. Finally, it summarizes a successful extended solution into concise steps. Each stage receives its own reward, giving the model more direct feedback on answering efficiently, recognizing mistakes and improving its reasoning.
In our experiments, Thinker-Task improved average accuracy across reasoning benchmarks from 45.9% to 51.0% for DeepSeek-R1-Distill-Qwen-1.5B. The benefits also extended to quick responses: Qwen2.5-1.5B’s fast-thinking mode achieved 25.2% accuracy using fewer than 1,000 tokens, close to the standard training baseline’s 25.6%. These results show how training intuition alongside deliberation can support both accurate reasoning and efficient answers.
We have released the training code and trained models so others can build on this work.
Publication update: Published at NeurIPS 2025